A page can be working perfectly one second and fail the next.
The main application has loaded. The user clicks a button that opens a feature loaded with import(). The browser requests the module, the connection briefly disappears, and the request fails.
That alone is not unusual. Networks fail. Wi-Fi changes. A laptop moves between connections. A server can briefly return an error.
The frustrating part came afterward.
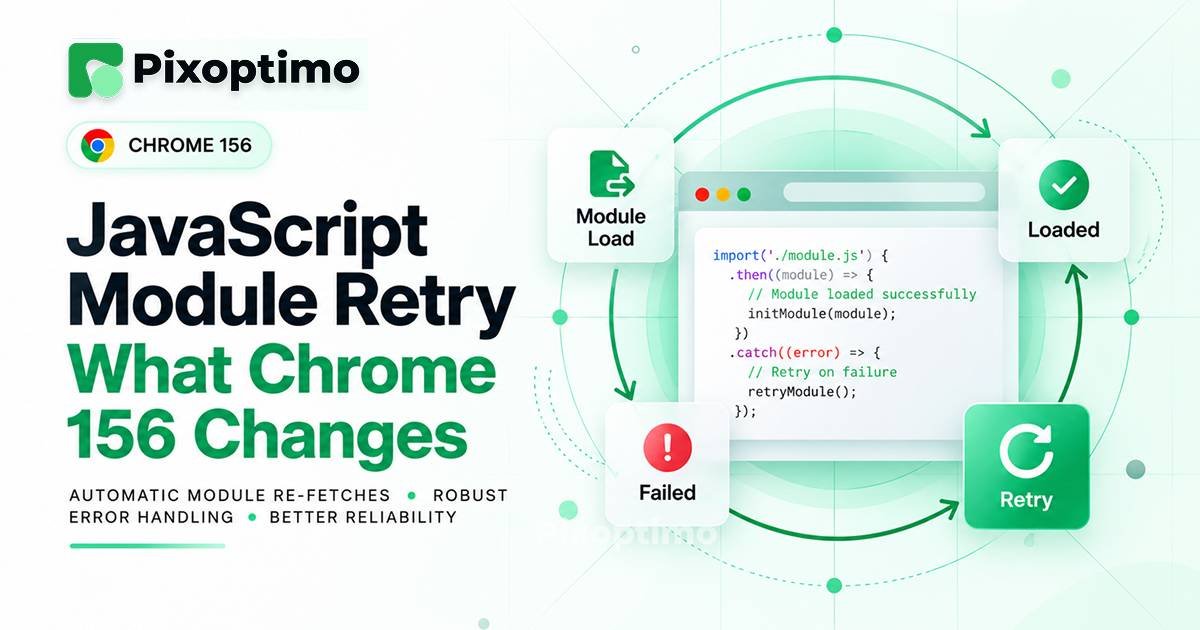
In Chrome’s previous module-loading behavior, a failed module load could be cached. Calling import() again did not necessarily give the browser a fresh opportunity to load the file. The application could offer a retry button while the browser effectively remembered the earlier failure.
Chrome 156 changes that behavior.
For developers using dynamic imports, that creates a small but useful new recovery option.
Quick Summary
- Chrome 156 changes how failed JavaScript module loads are handled.
- A failed module load can now be manually retried by calling
import()again.- This is particularly useful for applications that load features lazily.
- Chrome does not automatically build your retry UI or recovery logic.
- A retry still needs to make sense for the type of failure that occurred.
- Developers should test the behavior under unstable network conditions instead of assuming every failure is recoverable.
The problem was not really the import()
Dynamic imports are useful because an application does not have to download every piece of JavaScript immediately.
Imagine an analytics page inside an administration panel.
The dashboard itself loads first. Most users never open the analytics section, so there is little reason to download all of its code during the initial page load.
The application can wait:
const openAnalytics = async () => {
  const module = await import("./analytics.js");

  module.renderAnalytics();
};
When the user opens the feature, the browser retrieves analytics.js.
Normally, nothing interesting happens. The file arrives and the feature starts.
Now remove one ingredient: a reliable network connection.
The request can fail.
The application receives an error. Perhaps the interface displays:
Analytics could not be loaded.
That is already something developers have to handle.
But there was another problem hiding underneath.
If the user clicked the button again, the second import() could fail immediately because the earlier module failure had been cached.
So the application might have a perfectly reasonable retry action with a browser behavior that made the retry ineffective.
That distinction matters.
Chrome 156 changes the second attempt
Chrome 156 changes module loading so that failed module loads can be manually retried.
The practical mechanism is straightforward: the application can call import() again.
For example:
async function loadAnalytics() {
  try {
    const module = await import("./analytics.js");

    module.renderAnalytics();
  } catch (error) {
    console.error("Analytics failed to load", error);
  }
}
If the first attempt fails, calling the function again creates another opportunity for the module to load.
That does not mean the browser has suddenly become responsible for application-level error recovery.
It has not.
Chrome is changing a browser-level obstacle. The application still decides when to retry, whether to retry, and what the user sees while that happens.
That is an important boundary.
A retry button can finally mean what users think it means
Consider a temporary network interruption.
The user opens Analytics.
The module request fails.
The application shows a retry button.
They restore their connection and press it again.
That is a reasonable recovery flow.
Before Chrome 156, the browser’s handling of the failed module could undermine that experience. With the new behavior, another import() can actually be used as another attempt.
The UI does not have to become complicated.
async function tryAnalytics() {
  try {
    const analytics = await import("./analytics.js");

    analytics.renderAnalytics();
  } catch {
    showRetryMessage();
  }
}
The important part isn’t the button itself.
It is that the second attempt has somewhere useful to go.
But retrying does not fix every module failure
This is where it is easy to overstate the change.
Suppose analytics.js failed because the user’s Wi-Fi briefly disappeared. A retry could solve the problem.
Now consider a different situation.
The application was deployed incorrectly and the requested file no longer exists.
Retrying the same request will not repair the deployment.
Or perhaps the server is returning an error for every request. Repeating the request immediately only produces another failure.
The browser gives the application another chance. It does not tell the application whether that chance is worthwhile.
That decision remains yours.
Automatic retries need some restraint
It is tempting to turn the new behavior into an automatic loop:
tryImport();
tryImport();
tryImport();
tryImport();
That is rarely a good recovery strategy.
If the network is unavailable, repeated requests can create unnecessary traffic without improving the user’s situation.
A better approach is to decide what kind of recovery the application actually needs.
For a small UI feature, a single manual retry might be enough.
For a critical application module, you might want a controlled retry with a delay.
For something that is unlikely to recover without a new deployment, retrying may not make sense at all.
The browser’s ability to retry does not remove that design decision.
The deployment problem is still worth thinking about
There is another class of module-loading failure that has nothing to do with unreliable Wi-Fi.
Modern applications often use hashed JavaScript filenames.
A deployment might produce:
analytics.83f91.jswhile the previous version of the application was expecting:
analytics.61a42.jsIf an old page is still running and its requested file has disappeared from the server, a retry will not magically locate the new filename.
That is an application deployment problem.
The distinction is useful because both situations can appear to the user as:
Failed to load module.
The recovery strategy should not necessarily be the same.
Service workers can add another layer
Applications using service workers also need to understand where their JavaScript files are coming from.
A module request might pass through a service worker before reaching the network. Caching rules, stale assets, deployment timing and cache invalidation can all affect what the application receives.
Chrome 156’s module retry behavior does not replace good asset-versioning or service-worker strategies.
It simply makes another module-loading attempt possible after a failed load.
That is a smaller change than “Chrome now handles JavaScript errors automatically,” but it is also more useful because it tells developers exactly where the responsibility remains.
The feature is particularly interesting for lazy-loaded interfaces
The change matters most when JavaScript is loaded on demand.
That includes interfaces such as:
- large administration panels
- analytics screens
- editors
- account settings
- reporting tools
- feature-heavy web applications
- components that are intentionally excluded from the initial bundle
These applications frequently trade a larger initial download for smaller, targeted module requests later.
That is good for performance, but it also means a network problem can appear at an inconvenient moment.
The page may already look healthy.
Only one feature is broken.
That is exactly the kind of situation where a targeted retry can be preferable to asking the user to refresh the entire page.
Test the failure, not just the success
This feature is easy to understand when everything works.
That is not how it should be tested.
Open the application with the feature working.
Then simulate a poor connection.
Trigger the dynamic import.
Let the request fail.
Restore the connection.
Try the feature again.
Now watch what happens.
Does the interface give the user a useful recovery option?
Does the second import() actually get another chance?
Does the loading state disappear after success?
Does the application remain usable if the feature fails again?
These questions are more valuable than simply checking whether the code compiles.
A reliable error path should be tested as deliberately as the successful path.
A small helper can keep the application readable
There is no need to build a large abstraction just because a browser behavior changed.
A small helper may be enough:
async function loadModule() {
  return import("./analytics.js");
}

async function openAnalytics() {
  try {
    const analytics = await loadModule();

    analytics.renderAnalytics();
  } catch (error) {
    showRetryMessage(error);
  }
}
The retry action can call openAnalytics() again.
If the application eventually needs more sophisticated behavior, that logic can be added later.
Starting small is often better than building a generic “retry everything” system before the application actually needs one.
What Chrome 156 does not change
It is worth keeping the boundaries clear.
Chrome 156 does not:
- automatically retry every failed module
- decide whether a failure is temporary
- fix missing JavaScript files
- repair broken deployments
- replace application error handling
- guarantee that a second request will succeed
What it changes is narrower:
A failed module load can be manually retried instead of being trapped by the previous cached-failure behavior.
That is enough to make certain recovery flows more practical.
Why this small browser change matters
Browser features do not always arrive as dramatic new APIs.
Sometimes the useful change is removing a behavior that made an existing API frustrating to use.
Dynamic import() was already capable of loading JavaScript on demand. Developers already knew how to catch its errors. Applications could already display retry controls.
The missing piece was what happened when the browser remembered the failed module load.
Chrome 156 changes that part of the story.
For a user who loses their connection for a moment, the difference can be surprisingly simple:
Click retry. Try again. Continue working.
That does not sound like a major JavaScript feature.
From the perspective of someone staring at a broken application, it can be exactly the feature they needed.
The practical takeaway
If your application uses dynamic imports, you do not need to redesign it because Chrome 156 has changed this behavior.
But it is worth looking at your existing module error handling.
Search for places where your application does something like:
import("./feature.js")Then ask what happens when that import fails.
Does the user get stuck?
Does the entire page reload?
Is there already a retry action?
If there is a retry action, test whether it now provides the recovery experience you expected.
The browser can give a failed module another chance.
Your application still has to decide what that chance should look like.
That is the useful part of Chrome 156: not automatic retries, but a browser behavior that makes deliberate retry-based recovery possible.